
Automated Metadata Generation and ISO Standards Compliance with Python
1. Introduction
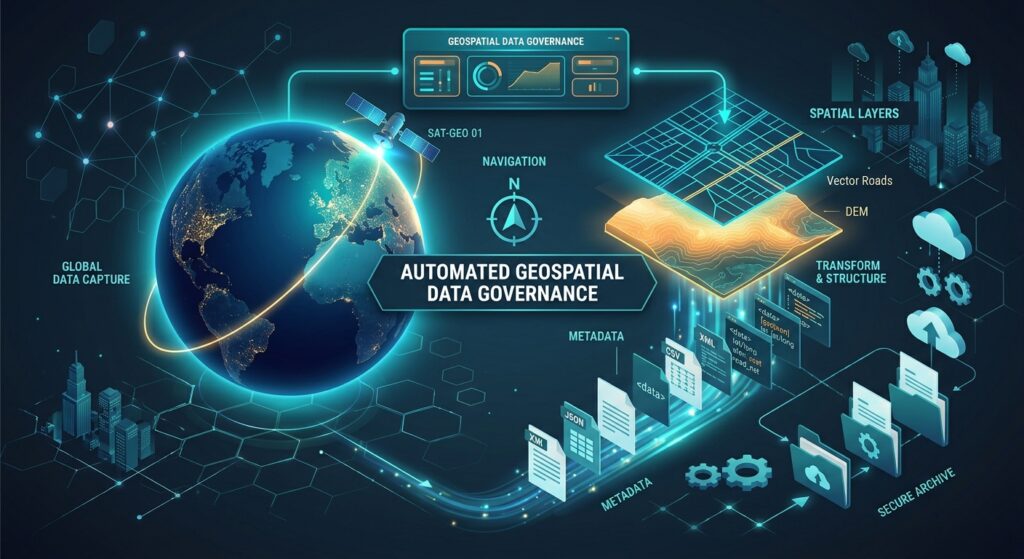
Mastering Automated Metadata Generation Python scripts helps organizations transition from manual documentation to automated spatial data governance. Spatial data pipelines frequently produce valuable datasets without producing the metadata needed to understand, maintain, discover, or reuse them. A workflow may generate a road network, a digital elevation model, a land-cover classification, or a collection of administrative boundaries, yet leave basic questions unanswered: Who created the data? What area does it cover? Which coordinate reference system does it use? When was the dataset updated? What do its attributes mean?
This problem becomes more serious as organizations accumulate hundreds or thousands of spatial files. Manually documenting every output is labor-intensive, and metadata maintenance is often overlooked when processing scripts change frequently.
Automated metadata generation using Python and ISO 19115 concepts helps address this problem by extracting technical properties directly from spatial files and converting them into standardized metadata records. Such automation supports dataset discovery, interoperability, auditability, and data governance.
Two standards are particularly relevant:
-
ISO 19115-1 defines the conceptual framework for describing geographic information and services, including identification, extent, quality, spatial reference, content, distribution, and other metadata properties.
-
FGDC CSDGM is the US Federal Geographic Data Committee’s Content Standard for Digital Geospatial Metadata. It remains a legacy standard, while FGDC guidance also encourages the use of endorsed ISO geospatial metadata standards.
For XML exchange, ISO 19115-3:2023 defines an XML implementation of ISO 19115-1 and ISO 19115-2. The examples below use pygeometa to generate ISO 19139 XML, an established encoding used in many existing GIS infrastructures. This is not the same as targeting the newer ISO 19115-3 XML implementation, so the required output schema must be selected according to the receiving organization’s profile.
This tutorial builds a metadata pipeline that:
-
Reads vector and raster datasets programmatically.
-
Extracts spatial bounds, CRS information, schemas, dimensions, feature counts, and filesystem timestamps.
-
Generates standardized JSON sidecars based on a defined organizational profile.
-
Creates ISO metadata control files that can be rendered into ISO 19139 XML after the required descriptive information has been reviewed.
-
Processes entire directories and records failures for investigation.
The core principle is straightforward: automate what the dataset can prove, and require human input for what the dataset cannot reliably tell you.
2. What information can be extracted automatically?
A useful spatial metadata record combines technical facts with descriptive and governance information.
| Metadata element | Extraction method | Automation suitability |
|---|---|---|
| Spatial bounding box | Fiona or Rasterio dataset bounds | High |
| CRS and EPSG code | Dataset CRS parsed using PyProj | High, when CRS metadata is present |
| Geometry type | Vector layer schema | High |
| Attribute names and data types | Fiona schema | High |
| Feature count | Vector layer count | High when supported by the driver |
| Raster dimensions and bands | Rasterio dataset properties | High |
| File size | Python filesystem metadata | High |
| Last-modified timestamp | Filesystem mtime |
High, subject to filesystem semantics |
| File creation timestamp | Platform-specific filesystem properties | Conditional |
| Dataset title | Filename, then curator refinement | Partial |
| Abstract and purpose | Data dictionary, project configuration, or curator | Requires authoritative input |
| Data creation or publication date | Source documentation or data registry | Requires authoritative input |
| Data lineage | Pipeline configuration, processing logs, or project records | Partial |
| License, ownership, and contact information | Organizational data-governance register | Requires authoritative input |
This distinction matters because a file’s last-modified timestamp does not necessarily indicate when its geographic content was collected or created. A GeoTIFF copied to another disk yesterday could contain imagery captured ten years ago.
Similarly, an EPSG code can be extracted only if the source CRS can be identified. A file without trustworthy CRS metadata should be flagged rather than assigned a guessed coordinate system.
3. Environment setup
Install the Python dependencies
Create an environment and install the libraries:
python -m venv metadata_envActivate it on Windows:
metadata_env\Scripts\activateOr on Linux:
source metadata_env/bin/activateInstall the packages:
python -m pip install fiona rasterio geopandas pyproj shapely pandas pyyaml pygeometaThe primary dependencies are:
-
fiona— reads vector layer bounds, geometry types, attribute schemas, and feature counts. -
rasterio— reads raster dimensions, bands, CRS, resolution, and geospatial bounds. -
pyproj— normalizes coordinate reference information and extracts EPSG identifiers when available. -
pygeometa— generates standards-based metadata from a Metadata Control File (MCF). -
pyyaml— writes and reads structured YAML metadata configuration. -
geopandasandshapely— useful for additional spatial inspection and validation.
pygeometa supports metadata creation through YAML-based Metadata Control Files and can generate ISO 19139 XML.
4. Step 1 — Read vector and raster datasets programmatically
Spatial metadata extraction starts by opening each dataset with the appropriate reader.
For vector data, Fiona exposes the layer schema, CRS, bounds, and feature count. For raster data, Rasterio exposes dimensions, band count, resolution, CRS, and bounds. Rasterio’s bounding box is derived from its geospatial transformation
Reading a vector layer with Fiona
import fionavector_path = "data/roads.gpkg"# A GeoPackage can contain more than one vector layer.layers = fiona.listlayers(vector_path)print("Available layers:", layers)# Read the first layer for demonstration.layer_name = layers[0]with fiona.open(vector_path, layer=layer_name) as src: print("Driver:", src.driver) print("CRS:", src.crs) print("Bounds:", src.bounds) print("Geometry type:", src.schema["geometry"]) print("Feature count:", len(src)) # Extract the attribute schema. for field_name, field_type in src.schema["properties"].items(): print(field_name, field_type)This code provides the technical foundation for an automated spatial metadata script.
The bounds generally take the form:
(minx, miny, maxx, maxy)These coordinates are expressed in the dataset’s CRS. They should not automatically be interpreted as longitude and latitude.
Reading a raster with Rasterio
import rasterioraster_path = "data/elevation.tif"with rasterio.open(raster_path) as src: print("CRS:", src.crs) print("Bounds:", src.bounds) print("Width:", src.width) print("Height:", src.height) print("Band count:", src.count) print("Resolution:", src.res) print("Data types:", src.dtypes) print("NoData values:", src.nodatavals)Unlike a vector dataset, a raster generally does not have a feature count. It has dimensions, pixel data types, and band information. A metadata pipeline should preserve those differences rather than forcing every dataset into the same schema.
5. Step 2 — Extract the bounding box, CRS, schema, and timestamps
The next stage normalizes the extracted information into a consistent internal representation.
5.1 Parse CRS information and calculate a geographic bounding box
A projected dataset might have coordinates in metres, while a geographic dataset might use longitude and latitude in degrees.
Store the original bounding box together with the CRS in which it is expressed. When possible, also calculate a WGS 84 bounding box for geographic discovery and standards-oriented metadata exchange.
Rasterio’s transform_bounds() transforms bounds between coordinate reference systems while densifying the edges to better account for nonlinear transformations.
from pyproj import CRSfrom rasterio.warp import transform_boundsdef extract_crs_metadata(crs_input): """ Normalize a CRS and extract its authority code when available. """ if not crs_input: return None try: crs = CRS.from_user_input(crs_input) authority = crs.to_authority() return { "authority": authority[0] if authority else None, "code": authority[1] if authority else None, "epsg": crs.to_epsg(), "wkt": crs.to_wkt() } except Exception: # Retain an explicit indication that CRS parsing failed. return { "authority": None, "code": None, "epsg": None, "wkt": str(crs_input), "parse_warning": "CRS could not be normalized" }def extract_bounds_metadata(bounds, crs_metadata): """ Store source-CRS bounds and, if possible, WGS 84 bounds. """ if bounds is None or crs_metadata is None: return { "source_crs": None, "wgs84": None, "warning": "Missing bounds or source CRS" } minx, miny, maxx, maxy = map(float, bounds) result = { "source_crs": { "minx": minx, "miny": miny, "maxx": maxx, "maxy": maxy }, "wgs84": None } try: left, bottom, right, top = transform_bounds( crs_metadata["wkt"], "EPSG:4326", minx, miny, maxx, maxy, densify_pts=21 ) result["wgs84"] = { "west_longitude": left, "south_latitude": bottom, "east_longitude": right, "north_latitude": top } except Exception as exc: result["warning"] = ( f"Geographic bounding box transformation failed: {exc}" ) return resultThis function deliberately keeps the original and transformed extents separate. That prevents a common metadata error: labeling projected coordinates as longitude and latitude.
For extremely large extents, datasets crossing the antimeridian, or unusual coordinate systems, inspect the transformed bounding box carefully. A bounding box is an approximation of the geographic footprint, and specialized datasets may need more careful extent processing.
5.2 Extract attribute names and data types
Attribute schemas are particularly useful when generating documentation for vector layers.
def extract_vector_schema(schema): """ Convert a Fiona schema into a serializable field list. """ fields = [] for field_name, field_type in schema["properties"].items(): fields.append({ "name": field_name, "source_type": str(field_type) }) return { "geometry_type": schema.get("geometry"), "fields": fields }For example, a roads layer might contain fields such as road_id, road_name, surface_type, and length_m. The script can extract their names and storage types without manually opening the dataset.
However, technical types do not necessarily explain the meaning of attributes. A field such as class = 2 still needs a data dictionary describing the meaning of value 2.
5.3 Extract filesystem timestamps
Python’s pathlib and os.stat() allow a pipeline to capture file size and modification times.
import osfrom datetime import datetime, timezonedef extract_file_metadata(path): """ Return filesystem facts without treating them as data lineage. """ stat = path.stat() modified_utc = datetime.fromtimestamp( stat.st_mtime, tz=timezone.utc ).isoformat() # A reliable filesystem creation timestamp is platform-dependent. if hasattr(stat, "st_birthtime"): created_timestamp = stat.st_birthtime elif os.name == "nt": # On Windows, st_ctime represents creation time. created_timestamp = stat.st_ctime else: # On many Unix filesystems, st_ctime means metadata-change time. created_timestamp = None created_utc = ( datetime.fromtimestamp( created_timestamp, tz=timezone.utc ).isoformat() if created_timestamp is not None else None ) return { "file_name": path.name,The script does not substitute filesystem timestamps for true dataset creation dates. That distinction is essential when preparing metadata records for formal publication or audit.
6. Step 3 — Format standardized metadata as JSON and ISO XML
A maintainable pipeline benefits from separating technical metadata extraction from the final output format.
The internal metadata record can be converted to JSON for automated catalogs and diagnostic review. A separate standards-specific step can use the same extracted facts to populate an ISO metadata template.
6.1 Define a JSON metadata profile
The following is an example of a local JSON metadata structure based on ISO 19115 concepts.
Important: This JSON structure is an organizational sidecar format, not by itself a formally validated ISO JSON encoding. JSON interchange should follow the specific profile and schema required by the receiving platform. ISO 19115-4 concerns a JSON implementation of metadata fundamentals and, as listed by ISO on October 20, 2026, is under publication.
{
  "profile": "organization-spatial-metadata-v1",
  "identifier": "urn:example:roads:metadata",
  "metadata_date_utc": "2026-10-20T08:00:00Z",
  "resource": {
    "title": "Road Network",
    "type": "vector",
    "abstract": "REVIEW REQUIRED: describe the dataset."
  },
  "spatial": {
    "source_crs": {
      "authority": "EPSG",
      "code": "32637"
    },
    "bbox_source_crs": {
      "minx": 200000.0,
      "miny": 9800000.0,
      "maxx": 220000.0,
      "maxy": 9820000.0
    },
    "bbox_wgs84": {
      "west_longitude": 36.0,
      "south_latitude": -1.8,
      "east_longitude": 36.2,
      "north_latitude": -1.6
    }
  },
  "content": {
    "feature_count": 15230,
    "geometry_type": "LineString",
    "fields": [
      {
        "name": "road_id",
        "source_type": "int"
      },
      {
        "name": "road_name",
        "source_type": "str"
      }
    ]
  },
  "file": {
    "file_size_bytes": 1250000,
    "filesystem_modified_utc": "2026-10-19T14:20:00+00:00",
    "filesystem_created_utc": null
  }
}
Illustrative example only; the displayed coordinates, counts, and dates are not extracted from a real dataset.
A JSON profile makes it easy to index metadata, compare datasets, detect missing CRS values, and generate reports. By assigning the profile a version number, an organization can update its field definitions without silently changing existing metadata records.
The generation code can then serialize the record:
import jsonfrom pathlib import Pathdef write_json_metadata(metadata, output_path): """ Write a UTF-8 JSON metadata sidecar. """ output_path = Path(output_path) output_path.parent.mkdir(parents=True, exist_ok=True) with output_path.open("w", encoding="utf-8") as file: json.dump( metadata, file, indent=2, ensure_ascii=False )6.2 Create an ISO Metadata Control File
For ISO XML, pygeometa uses a Metadata Control File (MCF). The MCF separates metadata content from the particular schema used to render it.
A simplified MCF template might look like this:
mcf:
  version: 2.0

metadata:
  identifier: "REPLACE-WITH-STABLE-RECORD-UUID"
  language: en
  charset: utf8
  hierarchylevel: dataset
  dates:
    creation: "2026-10-20"

spatial:
  datatype: vector
  geomtype: curve

identification:
  title:
    en: "Road Network"
  abstract:
    en: "REVIEW REQUIRED: describe purpose and content."
  dates:
    creation: "REVIEW REQUIRED: enter the actual dataset date."
  url: "REPLACE-WITH-DATASET-URL"
  rights:
    en: "REVIEW REQUIRED: enter the correct rights statement."
    url: "REPLACE-WITH-LICENSE-OR-RIGHTS-URL"
  status: completed
  accessconstraints: otherRestrictions
  extents:
    spatial:
      - bbox: [36.0, -1.8, 36.2, -1.6]
        crs: 4326

contact:
  pointOfContact:
    organization: "REPLACE-WITH-ORGANIZATION"
    url: "REPLACE-WITH-ORGANIZATION-URL"
    individualname: "REPLACE-WITH-RESPONSIBLE-PERSON"
    positionname: "REPLACE-WITH-ROLE"
    phone: "REPLACE-WITH-PHONE"
    fax: "REPLACE-WITH-FAX-OR-APPROVED-VALUE"
    address: "REPLACE-WITH-ADDRESS"
    city: "REPLACE-WITH-CITY"
    administrativearea: "REPLACE-WITH-REGION"
    postalcode: "REPLACE-WITH-POSTAL-CODE"
    country: "REPLACE-WITH-COUNTRY"
    email: "REPLACE-WITH-CONTACT-EMAIL"
This template shows the separation between automatically extracted properties, such as the extent, and the descriptive properties requiring an authoritative source.
The date under metadata.dates.creation refers to the creation of the metadata record. The date under identification.dates.creation refers to creation of the resource itself. They are not interchangeable. The second date must come from an authoritative data record or be reviewed before publication.
The bounding box provided to the MCF is expressed in WGS 84 coordinate order:
[west longitude, south latitude, east longitude, north latitude]
The corresponding source-CRS bounding box should also be retained in the internal JSON sidecar.
6.3 Generate ISO 19139 XML using pygeometa
After the MCF is populated with valid contact, rights, resource-date, and identification information, generate the XML document:
# Validate the Metadata Control File.
pygeometa metadata validate road_network.mcf.yml

# Generate ISO 19139 XML.
pygeometa metadata generate road_network.mcf.yml \
  --schema=iso19139 \
  --output=road_network_metadata.xml
The generated XML uses the selected pygeometa schema implementation rather than relying on manually assembled XML tags. This reduces the risk of incorrect namespace structures or missing standard-specific elements.
The generated XML should still be checked against the intended implementation schema and any organizational or national metadata profile. A valid MCF is not, by itself, proof that the resulting XML satisfies every requirement of the target metadata profile.
If the consuming system specifically requires ISO 19115-3:2023, configure a generator and validator that support that XML implementation. Do not label ISO 19139 output as ISO 19115-3 XML simply because both are associated with ISO geographic metadata.
7. Step 4 — Automate metadata generation across a directory
The following script combines the extraction functions into a batch workflow. It processes vector and raster files, saves JSON sidecars, and prepares MCF files for XML generation. When an authoritative ISO profile is configured, it can also generate ISO 19139 XML.
Configure the workflow
Create a folder structure such as:
gis_project/
├── spatial_data/
│   ├── roads.gpkg
│   ├── boundaries.geojson
│   └── elevation.tif
├── metadata_output/
└── metadata_harvester.py
The script below assumes that metadata_output is separate from spatial_data, which prevents generated metadata from being mistaken for new input data.
It handles common file-based vector formats and raster formats. For multi-layer GeoPackages, it creates one metadata record per vector layer.
Full batch metadata generator
Save the following as metadata_harvester.py.
import osimport jsonimport loggingimport uuidfrom datetime import datetime, timezonefrom pathlib import Pathimport fionaimport rasterioimport yamlfrom pyproj import CRSfrom rasterio.warp import transform_bounds# ---------------------------------------------------------# Configuration# ---------------------------------------------------------DATA_ROOT = Path("spatial_data")OUTPUT_ROOT = Path("metadata_output")VECTOR_EXTENSIONS = { ".shp", ".gpkg", ".geojson", ".json", ".gml", ".kml", ".fgb"}RASTER_EXTENSIONS = { ".tif", ".tiff", ".img", ".jp2", ".vrt", ".asc"}# Enter true organizational metadata before XML publication.# The default values intentionally leave publication disabled.ISO_PROFILE = { "resource_url": "", "resource_date": "", # Actual resource creation/publication date. "abstract": "", "rights": "", "rights_url": "", "lineage": "", "contact": { "organization": "", "url": "", "individualname": "", "positionname": "", "phone": "", "fax": "", "address": "", "city": "", "administrativearea": "", "postalcode": "", "country": "", "email": "" }}Run the batch processor
From the project directory, execute:
python metadata_harvester.pyWith the default settings, the script produces JSON sidecars and MCF drafts but does not publish ISO XML because the authoritative governance profile is intentionally incomplete.
A possible output structure is:
metadata_output/
├── roads__transport.mcf.yml
├── roads__transport.metadata.json
├── boundaries__admin.mcf.yml
├── boundaries__admin.metadata.json
├── elevation.metadata.json
└── elevation.mcf.yml
For a GeoPackage containing multiple layers, each layer receives its own metadata record. For a raster, the record contains its dimensions, number of bands, pixel data types, CRS, extent, and resolution rather than a vector feature count.
The script logs successful records and processing failures. In a production pipeline, send those logs to a centralized logging service or retain them as build artifacts.
Important review point: The MCF drafts intentionally mark unknown descriptive details for review. Do not publish them unchanged. Populate the responsible organization, contact information, rights, resource dates, abstract, lineage, and correct dataset URL. Set GENERATE_ISO19139_XML = True only after configuring an authoritative profile and reviewing the required fields. For datasets with different resource dates, use a per-dataset date registry instead of applying one date to every file.
8. Validation and enterprise best practices
Automating metadata creation is only one component of metadata governance. A reliable enterprise process also needs validation, provenance, change management, and clear responsibility for maintaining descriptive content.
Validate technical metadata before publication
At minimum, check that:
-
A spatial dataset has valid bounds.
-
The source CRS is present or explicitly flagged as unknown.
-
Geographic bounding boxes are correctly transformed.
-
Vector geometry types and attribute schemas can be read.
-
Counts and dimensions are plausible.
-
Filesystem dates are not mislabeled as acquisition or resource-creation dates.
-
Every generated record has a stable identifier within the organization’s identifier policy.
The example script creates a draft when the source data lacks a geographic extent. Such cases should be routed to review rather than published as complete spatial metadata.
Validate against the intended ISO implementation
ISO standards describe more than a list of fields. Their implementations and organizational profiles define the expected encoding, constraints, mandatory elements, code lists, and requirements for individual metadata records.
The ISO 19115-3:2023 implementation includes XML schemas and Schematron rules for constraints that XML schema validation alone does not cover.
A production quality-control stage should therefore distinguish:
| Validation level | What it establishes |
|---|---|
| Parsing | Metadata JSON, YAML, or XML is readable |
| Structural validation | Required fields and organizational data types are present |
| Schema validation | XML or JSON satisfies the selected schema |
| Profile validation | Organization-specific rules and controlled vocabularies are satisfied |
| Governance review | Rights, lineage, purpose, and responsible parties are accurate |
A record can pass structural validation and still fail a profile requirement or contain inaccurate descriptive information.
Capture lineage directly from the processing pipeline
The most reliable time to document data lineage is while the data is being generated.
For example, a DEM-processing workflow already knows which source raster was used, which interpolation method was applied, what parameters were selected, and which software version performed the operation. Capturing these details at runtime is more dependable than trying to reconstruct them from the output file later.
Useful lineage information includes source dataset identifiers, processing timestamps, software and version numbers, transformation parameters, data-quality checks, and references to reproducible processing scripts.
Version the metadata profile
Treat the metadata profile as a maintained software interface. Keep its definition in version control, define required and optional fields explicitly, and document changes to field names or meanings.
The profile should also specify how identifiers are generated, how dates are interpreted, which CRS representations are allowed, and how missing values should be reported.
Integrate metadata generation into CI/CD
For recurring spatial ETL workflows, metadata creation should run automatically when a dataset is produced or updated.
A typical process is:
1. Spatial data processing
Produce raster and vector outputs.
2. Metadata harvesting
Extract extent, CRS, schema, counts, and timestamps.
3. Validation and review
Check schemas, descriptive content, lineage, and rights.
4. Standards-based export
Generate XML or JSON for the selected profile.
5. Publication and registry update
Publish validated records alongside discoverable datasets.
The pipeline should fail or quarantine a record if a mandatory requirement is not satisfied. Metadata generation should not silently fabricate a CRS, responsible party, creation date, license, or processing history just to make a file pass validation.
9. Conclusion
Automated metadata generation with Python reduces repetitive documentation work and makes spatial data pipelines more consistent. Fiona and Rasterio supply technical facts about vector and raster datasets; PyProj helps normalize coordinate systems and spatial extents; and YAML-based metadata control files provide a maintainable path to standards-oriented XML generation.
The strongest approach is to separate automatic extraction from human-authored governance information, validate each metadata record against its intended standard and profile, and integrate these checks into the same pipeline that produces the spatial data.
For organizations managing large GIS inventories, this turns metadata from a neglected final task into a reproducible part of data production, quality assurance, and publication.